
A year ago, a small business wanting generated images had one or two sensible options. Now there are many credible models from OpenAI, Google, Black Forest Labs, ByteDance and Microsoft AI, each with different strengths, and new versions arrive every few weeks. For a team without a dedicated designer, the choice itself has become a time sink.
Here is a comparison method that takes an afternoon, uses your own work rather than marketing galleries, and produces a decision you can defend.
Step One: Collect Ten Real Briefs
Do not test with prompts like “a cat astronaut”. Pull ten images your team actually needed in the last two months: a blog header, a product background, a social post for a promotion, an illustration for a how-to guide, a banner for a newsletter. Write each as the brief you would give a freelancer.
Real briefs expose the differences that matter to you. One model may excel at photographic product scenes and struggle with flat illustration; another may follow long, detailed instructions closely but produce a recognisable house style you do not want.
Step Two: Run the Same Briefs Through Three Models
Pick three candidates. Using them through an API rather than three separate consumer subscriptions keeps the test cheap and fair, because you control the exact prompt and settings for each.
Aggregation platforms that expose several image models behind one account make this especially easy — the MAI Image 2.6 API can be tested alongside competing models with the same key and the same request format, and each image is billed individually rather than through a monthly plan.
Generate two or three outputs per brief per model. A single output per brief is too noisy to judge.
Step Three: Score What Your Business Cares About
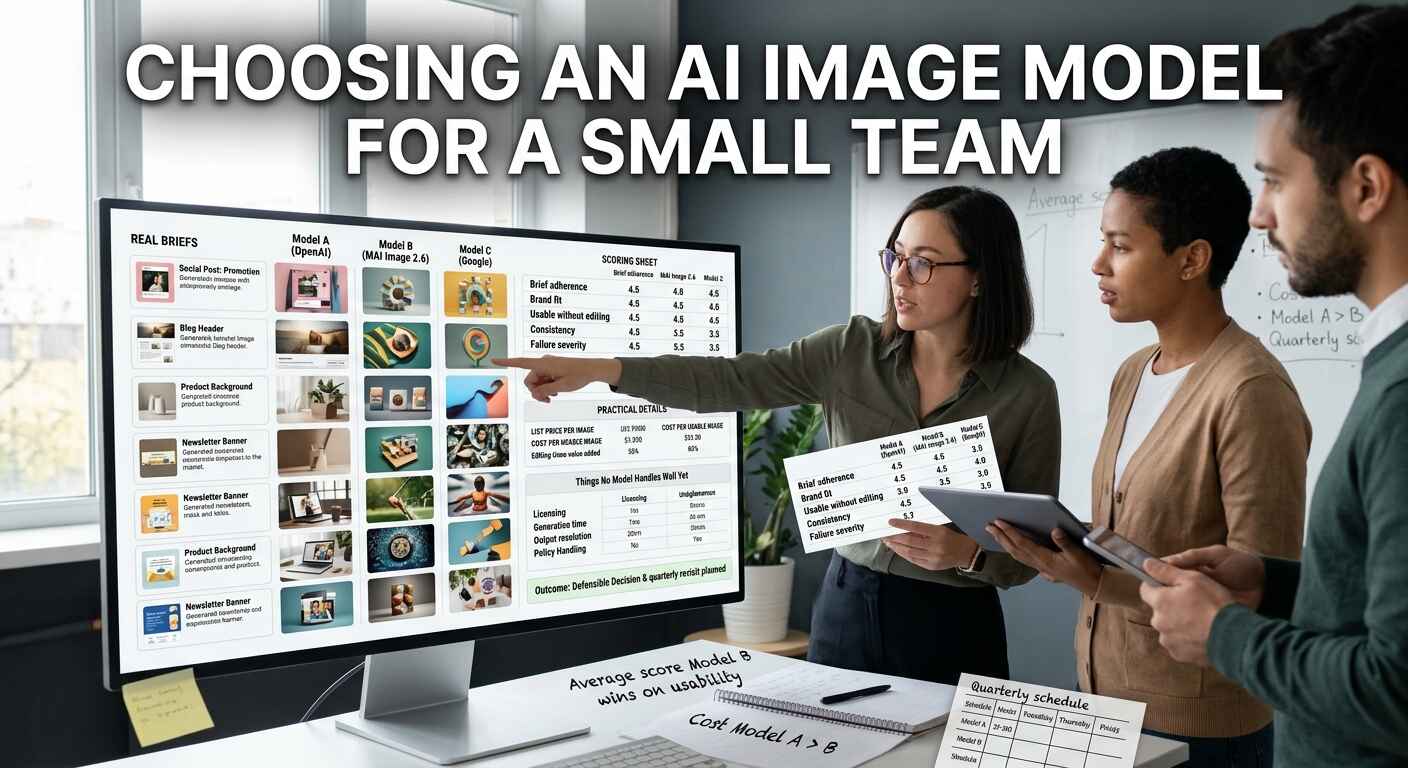
Create a simple scoring sheet with five columns, each scored one to five.
- Brief adherence. Did it produce what was asked, including composition and the specific details?
- Brand fit. Would this sit comfortably next to your existing visuals without looking out of place?
- Usable without editing. Could it be published after a crop, or does it need retouching?
- Consistency. Do the repeated outputs for the same brief look like they belong together?
- Failure severity. When it went wrong, was it a small flaw or something unusable?
Have two people score independently and average. You will be surprised how often a model that wins the “wow” test loses on usability.
Step Four: Work Out Real Cost Per Usable Image
List prices per image differ between models, but the number that matters is cost per image you would actually publish. Divide the total spend for each model by the number of outputs that scored four or five on “usable without editing”. A cheaper model with a lower hit rate can easily cost more per usable image than a pricier one.
Add a rough value for editing time too. Twenty minutes of retouching per image is a real cost for a small team, and it usually outweighs the per-image price difference.
Step Five: Check the Practical Details
Before settling on a winner, confirm the unglamorous parts. Check the licensing terms for commercial use of outputs, since they vary between providers. Check typical generation time, because a model that takes a minute per image changes how your team works compared with one that returns in seconds.
Check the output resolution and aspect ratios supported, especially if you publish to several channels with different formats.
And check how the provider handles content policy refusals, so a routine product-background request does not get blocked unexpectedly on deadline day.
Things No Model Handles Well Yet
Keep a few categories out of the test entirely, because the answer is the same everywhere. Images where readable text is essential should have text added afterwards in a design tool.
Images of your real products, staff or premises should be photographs. A set of images showing the same character across several scenes will need significant manual work regardless of model.
Revisit Quarterly, Not Weekly
New model releases are constant, and chasing each one burns the time the process was meant to save. Keep your ten briefs and scoring sheet, and rerun the comparison once a quarter or when a release looks relevant to your specific use case. Switching is cheap when you access models through an API, so the decision never locks you in.
The Outcome
At the end of the afternoon you have a scored comparison on your own work, a real cost per usable image, and a clear default model for everyday requests — plus a second model for the category where the first one is weak. That is a better foundation than whichever tool happened to be bundled into the software you already pay for.
